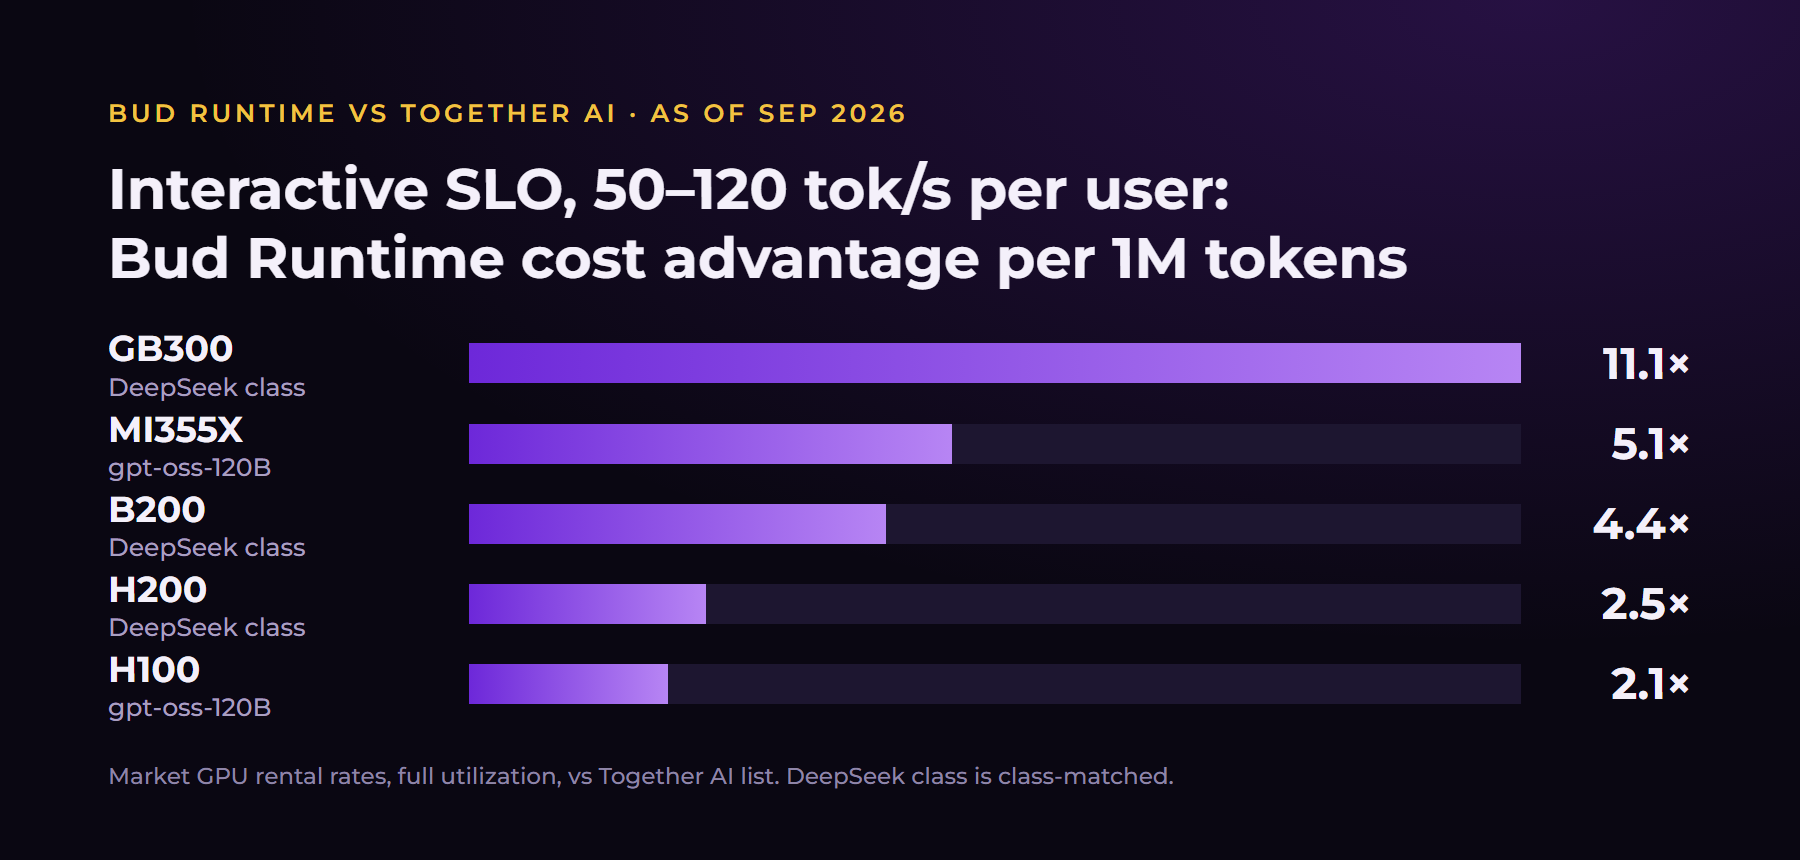
Across 14 comparable scenarios against Together AI, Bud Runtime leads 10, Together AI leads 3, and one is a tie. Under an interactive SLO of 50–120 tok/s per user, the regime that serves chat, copilots and coding agents, Bud Runtime leads every cell on GB300, B200, H200, MI355X and H100 at 2.1× to 11.1× lower cost per token. Together AI publishes no figure in that regime at all.
Figures are from Bud Ecosystem's benchmark report of 14 September 2026; Together AI figures are from its published rate card and benchmarks as of September 2026. The full report is a PDF download.
How we compared
A throughput number means nothing without the service level it was measured at. Every result sits in one of three SLO regimes, plus training, and regimes never share an axis.
- R1, single-user latency. Batch of one, in tok/s per user: voice, live assistants, latency-bound interfaces.
- R2, fixed interactivity. Tok/s per GPU while every user holds 50–120 tok/s: chat, copilots, coding agents.
- R3, saturated throughput. Tok/s per GPU at full batch: offline scoring, RAG indexing, evaluation, synthetic data.
- Training and engine index. 70B training throughput, and an engine-generation index on Hopper.
A batch-of-one number and a saturated number measure different things; one chart holding both flatters whoever picks the axis.
Cost per 1M tokens is the GPU-hour rate times the GPU count, divided by tokens produced per hour. Bud Runtime is costed at market GPU rental rates (July 2026: $1.17 per GPU-hour for H100, $1.73 for B200, $1.50 for MI355X; $1.17–$2.31 across the fleet) at full utilization. Together AI is costed at its own published prices: serverless list prices, blended 3:1, and dedicated rates of $8.99 per GPU-hour on B200 and $5.49 on H100, which are 5.2× and 4.7× the market rate.
Normalization by memory bandwidth separates silicon from software: tok/s per GPU divided by HBM TB/s. On gpt-oss-120B, MI355X leads H100 by 3.08× as measured but 1.29× per TB/s, so most of that headline is the memory bus. GB300 over B200 is 3.33× on DeepSeek-R1 at 70 tok/s per user with both at 8 TB/s, so that multiple is entirely interconnect and software.
| Regime | Scenarios | Bud Runtime | Together AI | Tie |
|---|---|---|---|---|
| R1 · batch of one | 3 | 2 | 1 | 0 |
| R2 · fixed interactivity, 50–120 tok/s/user | 5 | 5 | 0 | 0 |
| R3 · saturated | 4 | 2 | 1 | 1 |
| Engine index and training | 2 | 1 | 1 | 0 |
| Total | 14 | 10 | 3 | 1 |
Table 1 — scenarios led, by SLO regime. Together AI leads DeepSeek speed in R1, first-token latency in R3 and 70B training on B200; the R3 tie is on tokens per GPU.
Key results
Interactive chat and agents
Together AI publishes nothing in this regime. Against Together's list price, Bud Runtime is 11.1× cheaper per token on GB300 ($0.178 vs $1.98 per 1M, DeepSeek class), 4.4× on B200 ($0.454), 2.5× on H200 ($0.803), 5.1× on MI355X ($0.052 vs $0.262, gpt-oss-120B) and 2.1× on H100 ($0.124).
The fastest and cheapest figure in the report sits here: DeepSeek-V4 Pro at 11,200 tok/s per GPU on GB300 at 50 tok/s per user, for $0.057 per 1M tokens. Tightening DeepSeek-R1 from 59 to 98 tok/s per user, GB300 retains 64% of its throughput (3,602 to 2,307 tok/s per GPU) and H200 36% (422 to 152).
Batch and offline throughput
On gpt-oss-120B, the one model compared on identical open weights and precision, Bud Runtime delivers 7,236 tok/s per GPU on a saturated B200 at $0.066 per 1M, against Together's $0.262 list price: 4.0× lower. On Kimi K2.5 agentic coding, both sides deliver an identical 10,417 tok/s per GPU on 4×B200, a tie on throughput, and Bud Runtime's cost is $0.046 per 1M against $0.240: 5.2× lower.
Long context
At 128k tokens in and 8k out, DeepSeek-R1 on GB300 runs at 226 tok/s per GPU for $2.84 per 1M tokens: repository-scale coding, document analysis, legal and research work. Together AI publishes no comparable figure, so this is a data point, not a head-to-head result.
Small dense models
Llama 3 8B, saturated on a single H100, runs at 16,200 tok/s per GPU for $0.020 per 1M tokens: classification, routing, guardrails and extraction at volume. Together's only H100 figure is a 2024 batch-of-one number, which cannot sit on this axis. On the Hopper engine index for Llama 70B, Bud Runtime's vLLM V1 path is at 4.59× the vLLM 0.5.1 baseline, against the 4.0× Together claimed against the same baseline in July 2024.
Where Together AI leads
Together AI leads three scenarios, all on B200.
- Batch-of-one decode on DeepSeek. Together's ATLAS adaptive speculator reaches 501 tok/s per user on 4×B200 (DeepSeek-V3.1, FP8), against Bud Runtime's 368 on 8×B200 (DeepSeek-R1, NVFP4, TensorRT with multi-token prediction). That is 1.36× faster on half the GPUs; in GPU-seconds per token it is 7.98 ms against 21.7 ms, a 2.72× lead. Bud Runtime reaches 73% of Together's speed. Priced at the rate each operator pays, Together's tokens cost $19.94 per 1M against $10.45, or 1.9× more. Against the physical decode ceiling, ATLAS reaches 58% and Bud Runtime's path 11%: the largest unrealized headroom in the report, and Bud's to close.
- Time to first token under agentic load. On Kimi K2.5 agentic coding on B200 (45k–200k-token prompts, p50), Together reaches first token in 0.71 s against Bud Runtime's 1.10 s, 1.55× faster at identical delivered throughput. That speed comes at 5.2× the cost per token: $0.240 per 1M against $0.046.
- 70B training on B200. Together reaches 15,264 tok/s per GPU. Bud Runtime has no figure on that hardware. Both training paths build on the same open foundation, so the report attributes the gap to tuning rather than architecture.
The report projects how the first two gaps could close. Those are projections, not measurements, and none is counted here.
| Scenario | Metric | Together AI | Bud Runtime | Leads by |
|---|---|---|---|---|
| B200 · Kimi K2.5R3 | TTFT p50 | 0.71 s | 1.10 s | Together AI1.55× |
| B200 · DeepSeekR1 | tok/s per user | 501 (4 GPU) | 368 (8 GPU) | Together AI1.36× |
| B200 · DeepSeekR1 | GPU-s per token | 7.98 ms | 21.7 ms | Together AI2.72× |
| B200 · 70B trainingT | tok/s per GPU | 15,264 | — | Together AI |
| H100 · Llama 70Bindex | vs vLLM 0.5.1 | 4.00× | 4.59× | Bud Runtime1.15× |
| B200 · DeepSeekR1 | $/1M | $19.94 | $10.45 | Bud Runtime1.9× |
| H100 · gpt-oss-120BR2 vs list | $/1M | $0.262 | $0.124 | Bud Runtime2.1× |
| H200 · DeepSeek classR2 vs list | $/1M | $1.98 | $0.803 | Bud Runtime2.5× |
| B200 · gpt-oss-120BR1 | tok/s per user | ~187 (shared) | >500 (dedicated) | Bud Runtime~2.7× |
| B200 · gpt-oss-120BR3 vs list | $/1M | $0.262 | $0.066 | Bud Runtime4.0× |
| B200 · DeepSeek classR2 vs list | $/1M | $1.98 | $0.454 | Bud Runtime4.4× |
| MI355X · gpt-oss-120BR2 vs list | $/1M | $0.262 | $0.052 | Bud Runtime5.1× |
| B200 · Kimi K2.5R3 | $/1M, same throughput | $0.240 | $0.046 | Bud Runtime5.2× |
| GB300 · DeepSeek classR2 vs list | $/1M | $1.98 | $0.178 | Bud Runtime11.1× |
Table 2 — every admissible head-to-head comparison in the report, Together AI leads first. Together's batch-of-one lead on DeepSeek appears twice, as speed per user and as GPU-seconds per token. On narrow screens the table scrolls sideways.
Why the results come out this way
An open engine stack, not a closed fork. Bud Runtime composes the public engine frontier (TensorRT-LLM, Dynamo, vLLM, SGLang and LMCache) rather than forking it. Of the seventeen optimization families the report catalogs, six are published work both engines apply, and they cancel. Bud Runtime applies eight more that Together does not disclose or does not sell: non-prefix KV reuse, wide expert parallelism, sparse attention, KV tiering, custom drafts, configuration search, Blackwell Ultra and AMD. Together holds one that Bud Runtime does not, its runtime-learning speculator, and that one component is where its measured inference leads originate. Gains compound: DeepSeek-V4 Pro went from day zero to 11,200 tok/s per GPU in eight weeks on unchanged GB300 hardware, 5.1×.
Seven hardware families against two. Bud Runtime deploys on H100, H200, B200, GB300/B300, MI355X, MI325X and Ascend, with measured evidence on six. Together publishes performance on B200 and H100, lists GB300, B300 and H200 as contact-sales, and does not offer AMD. On gpt-oss-120B, MI355X returns 5,387 tok/s per dollar of hourly rental, against 4,183 on B200 and 2,241 on H100. The cheapest cell is on hardware Together does not sell.
Configuration is selected, not hand-tuned. Optimizations invert: EAGLE chain speculation is 1.96× at batch 1, 1.4× at batch 32, and 0.95×, a net loss, for wide trees at batch 64. Bud Simulator searches engine, precision, parallelism, speculation, cache policy and hardware against the model, workload and SLO, and returns the operating point and cost per million before deployment.
The operator captures engine gains, not the vendor. Market rates of $1.17–$2.31 per GPU-hour against Together's dedicated $5.49–$8.99 are a 4.7–5.2× gap before a single engine difference is counted, and the report is direct that this multiple, not the engine, accounts for most of the delivered cost gap. On Bud Runtime, a 30% throughput gain is a 23% cost cut for the operator; inside a managed endpoint it widens the vendor's margin and list price stays put. For a cloud provider reselling at Together's own list price, Bud Runtime returns 53–91% gross margin at full utilization, and 97% on DeepSeek-V4 Pro.
State the model, the workload and the SLO. Bud Simulator returns the configuration, the hardware and the cost per million tokens before you deploy.
Sovereign models on day zero
Sarvam 30B and Sarvam 105B were released on 6 March 2026 under Apache 2.0, with weights on Hugging Face and AI Kosh: sparse mixture-of-experts models trained end to end in India for Indian languages.
SGLang carried them on release day. The vLLM path shipped at launch as a fork and hot-patch and was upstreamed afterwards. Bud Runtime composes both engines, so day-zero support in either is day-zero support on Bud Runtime, with no bespoke serving stack and no vendor queue. Gnani.ai's Inya VoiceOS, a 5B speech-to-speech model covering more than fifteen Indian languages, launched under the IndiaAI Mission in February 2026, sits in the same category.
Together AI's catalogue, as verified in September 2026, carries no Sarvam, Gnani or BharatGen model, and offers no route to add one. For an Indian enterprise, CSP or government buyer under a sovereign-model mandate, that is not a performance difference. It is the difference between deployable and not deployable, and no rate card or benchmark compensates for it.
Caveats and scope
- Cost results assume market rental rates and sustained utilization. Below roughly 45% duty on Hopper, Together's list price is cheaper. The break-even sits at 9% on GB300 and 20% on MI355X.
- DeepSeek-class cost comparisons are class-matched, not identical models. They set Bud Runtime's R1-class deployments against Together's DeepSeek V4 Pro list price.
- gpt-oss-120B is the only exact like-for-like comparison, on identical open weights and precision.
- Together AI figures are from its published rate card and benchmarks as of September 2026. Bud Runtime market rates are from July 2026.
- Projections are excluded. The report's projected results are not measurements, and none is used here.
Source: Bud Ecosystem, "Inference performance evidence", 14 September 2026. Bud Runtime at July 2026 market GPU rental rates and full utilization; Together AI at its September 2026 rate card and published benchmarks, list prices blended 3:1. No projected figure is used as a result.