Turn deployed GPU capacity into a platform that scales with demand.
Bud GPU Foundry is the GPU-as-a-service control plane. It runs the accelerators you already own as governed services — from bare metal to tokens — with one catalog, one permission model, one audit trail and one bill. Silicon to outcomes, fully integrated. Open source under Apache 2.0.
Silicon to outcomes, as one integrated stack.
Bud GPU Foundry runs the accelerators you already own, across every cluster and site you register, and sells them as governed services — bare metal, virtual machines, Kubernetes, SLURM and serverless containers — to every tenant you serve, from a single node to a whole cluster, in one click. Then it keeps going, into inference, model services and token-based AI consumption on the same stack.
The platform is what was missing.
Accelerators arrive faster than the means to sell them well. Everyone who wants them wants something different — and serving each request separately leaves several stacks, several bills and no honest answer to who used what.
Bare metal
- A physical accelerator host, your OS, nobody else resident
- Provisioned in one workflow, power and break-fix as API calls
- Returned only after verified erasure, with evidence
Virtual machines
- Accelerators passed through at the hardware level
- Console that does not need the guest · snapshots · private images
- Placed by topology, not by count
Kubernetes
- Conformant upstream, a control plane you hold
- Accelerator node pools drawn from the same catalog
- Access brokered just in time — no standing kubeconfig
SLURM
- Login nodes, partitions and accounting, your accelerators behind them
- Keep your job scripts, module trees and workflows
- Accounting reconciled to the platform's own record
Serverless containers
- Declare an image, a command and a shape — the platform resolves the rest
- Stop is previewed before it happens; a queue is never silence
- Leases, schedules and idle thresholds release what is not working
Many tenants, nothing else shared
- Every unit names one isolation claim — about that unit, not the platform
- Service providers are offered only hardware- or fabric-enforced grades
- Resellers, sub-organizations and white-label on the same tree
Bare metal
Your service. Your invoice.
- Bud GPU Foundry is Layer 02 of the Bud Novaria AI OS stack — the GPU cloud layer. The capacity is installed; the platform was what was missing. A training team wants nodes and a scheduler, a platform team wants Kubernetes, an ISV wants a machine it can image, a research group wants a container and a notebook, a product team wants an endpoint and a token price. Bud GPU Foundry serves all of them from one fleet across five silicon vendors — NVIDIA, AMD, Intel, Qualcomm, Huawei — with one catalog, one permission model, one audit trail and one invoice.
- One click, any shape: a tenant asks for a shape (cards, memory per card, interconnect); the platform filters to what that organization may buy, picks exactly one unit by a published rule and says which rule chose it, places the work by topology — the project's region, then clusters with placeable headroom, then the right silicon — and metering starts when the unit is healthy. Nothing before healthy is ever charged.
- Five service classes from one catalog — bare metal (sole occupancy, metered in node-hours), virtual machines (no shared kernel, allocation-seconds), Kubernetes (a conformant cluster of your own, access brokered just in time), SLURM (partitions, QoS and fair share, accounting reconciled to the platform's record) and serverless containers (scale to zero, wake on demand, stop previewed before it happens) — plus the tenancy model: five isolation grades, strongest first, with service providers offered only hardware- or fabric-enforced grades, and resellers, sub-organizations and white-label on the same tree.
- Operator controls make the fleet a business: isolation graded per unit, quota you can sell, metering and invoices read from the same phase log the console shows, resellers and white-label, an audit trail and evidence — for enterprises running chargeback by project and department, and for service providers and neoclouds serving mutually untrusting tenants on prepaid or contract billing.
- The payoff: your silicon, your service, your invoice. Silicon to outcomes, fully integrated. Open source under Apache 2.0.
Installs into your own clusters — on-premise, in colocation, in sovereign and air-gapped environments. No component needs the public internet to serve a tenant.
Idle accelerators become a governed service.
Everything between the accelerator and the invoice is one product: the ways tenants reach the platform, the control plane, the data plane, the site fabric, and the revenue record that ties them together. Adding a new way to consume the fleet never adds a second billing path or a second permission model. That is what keeps the platform governable as it grows from one rack to many sites — and what lets AI services run on top as a tenant, inheriting every guarantee.
A cloud your customers trust, and your finance team can defend.
Most GPU platforms are assembled from schedulers, provisioning scripts and billing add-ons that were never designed to agree. The result is capacity on a dashboard that cannot be placed, charges for starts that never came up, and machines passed to the next customer with no proof they were wiped. Bud GPU Foundry owns the whole lifecycle instead, for three kinds of operator.
GPU cloud and service providers
Sell to independent, mutually untrusting customers with isolation enforced in hardware or the fabric, prepaid and contract billing, spend caps and a full enforcement ladder.
Enterprises and sovereign operators
Share one fleet across business units with chargeback by project and cost center, residency enforced at placement, and air-gapped deployment as a supported configuration.
Resellers and channel partners
Nest customer organizations, divide quota in whole units, apply your own brand and domain, and rate a replayable usage feed in your own billing system.
Describe the shape your work needs. Receive exactly one unit.
The platform filters the catalog to what your organization may buy, picks one unit by a published rule, tells you which rule chose it, and places the work — on one node, or gang-scheduled across many with the fabric in mind.
no_offered_sku names the nearest units and what each one lacks; queued is a position in line with a reason, never silence.Filtered before it is displayed
What a project's organization may actually buy is decided by its tenant class and isolation ceiling before anything is shown. Units weaker than the ceiling are never offered — not even as alternatives.
Placed by topology, not by count
The project's region, then only clusters that could place this grade and shape right now, then the one with the most headroom, then cards that share a link and a socket at the bandwidth sold. Gang-scheduled work starts all-or-nothing.
Everything the console does, from a script or an agent
The API is the product. Console, command line, Python and TypeScript SDKs and an infrastructure-as-code provider are generated from one specification, and a tool server lets an autonomous agent use the same operations under the same audit trail.
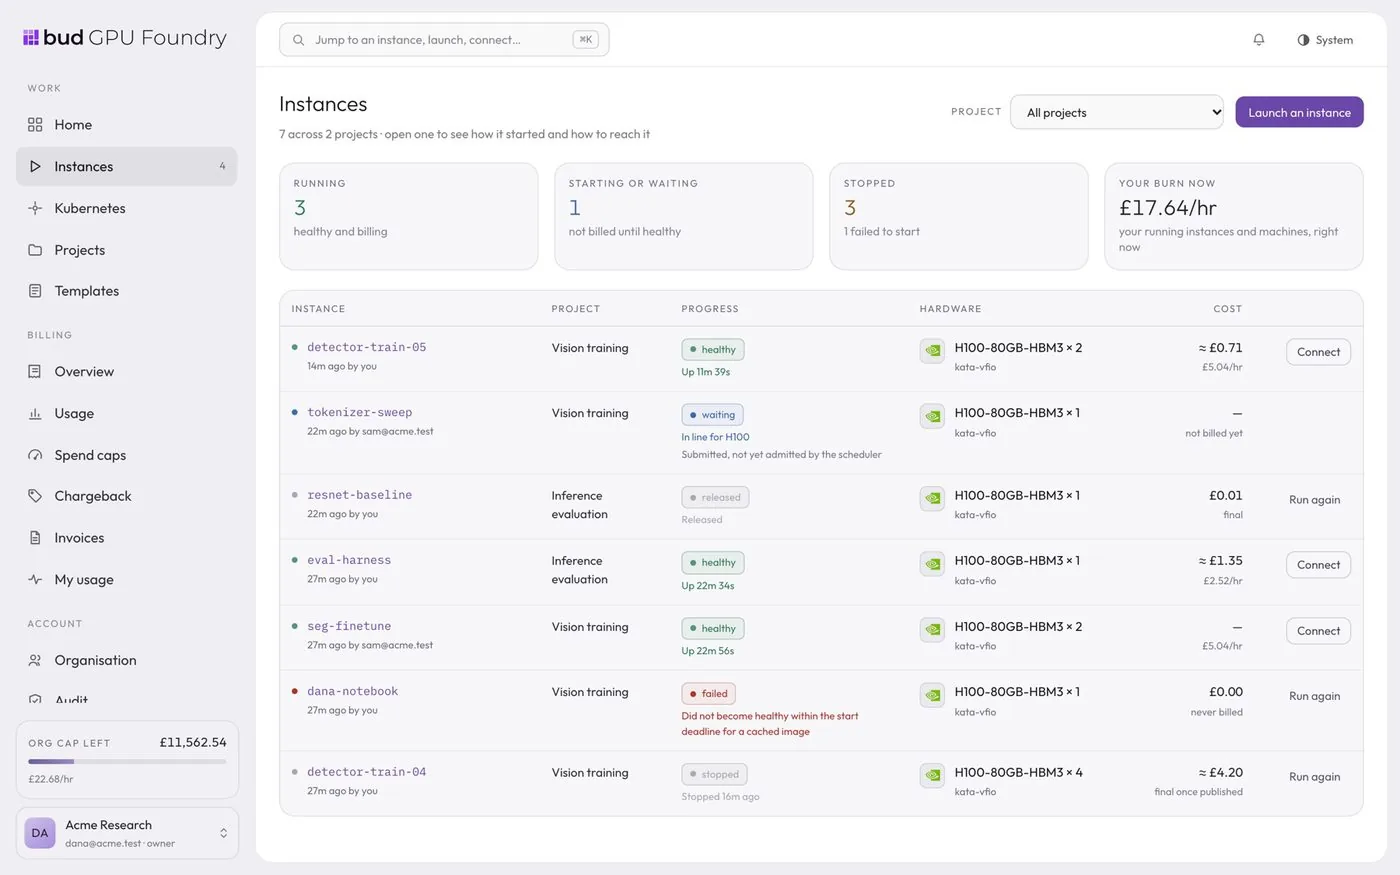
Metering starts when what you bought answers. Not a second before.
State is observed from the hardware, never assumed from intent. Three records exist for everything the platform has ever accepted, kept apart on purpose — what was asked for, what was observed, what was billed — and the screen a tenant reads and the invoice they receive come from the same log.
A failure is a record, not a gap
Everything that reached admission produces an allocation record, including what failed. An absent record and a zero record are different facts, and the platform keeps the difference. Reasons come from one closed vocabulary:
start deadline exceeded,image pull failed,device never attached— each charged nothing.Published start deadlines
One deadline for a start whose image was already resident, a longer one for a start that had to fetch it. Missing it terminates the allocation, reports a machine-readable reason and charges nothing.
Replay cannot double-charge
A metering event's identity is a pure function of the allocation and its window bounds, so a replay after a broker failure is a no-op rather than a second row. Completeness is verified by an independent nightly recomputation rather than asserted.
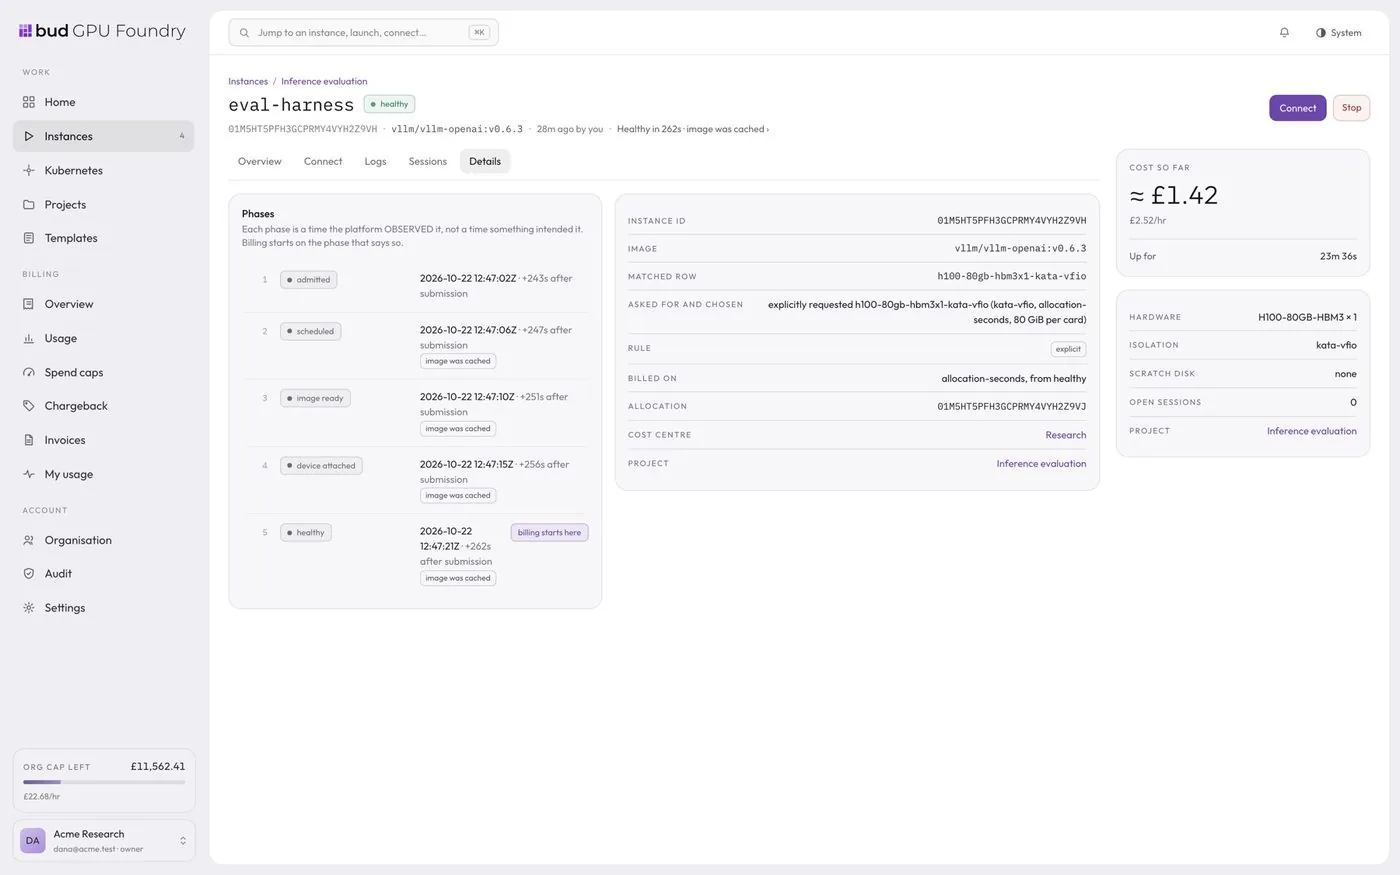
What makes the fleet a business.
Schedulers share a cluster; a control plane sells one. These six are the difference between hardware your teams queue for and a service every tenant consumes — and every one of them is a property of the platform, not a process running alongside it.
Any silicon, every site
Operationalise NVIDIA, AMD, Intel, Qualcomm and Huawei accelerators, mixed vendors and generations, as a single governed pool. Register another cluster at runtime and quota, placement, addressing and billing extend to it without a second deployment.
Metering starts at healthy
Seven lifecycle phases are recorded; the charge starts at exactly one — healthy — and a failure is a zero-cost record with a reason from one closed vocabulary. Time spent provisioning, pulling images or failing to start is never charged, on any unit, under any circumstance.
Many tenants, nothing else shared
Every sellable unit names one isolation grade, ranked strongest first. An operator states once that an organization may buy nothing weaker than a given grade, and every request is measured against it. For service providers whose customers may be rivals, shared-kernel grades are withheld by the platform, not by guidance.
Serverless that scales to zero
Models and workloads appear when called, release when idle, and chain into compound AI systems. Leases, schedules and idle thresholds release capacity that is not working — each previewed like a manual stop, so nothing is lost that was not stated first.
From capacity into AI consumption
Model catalogs, inference endpoints, serverless models and token metering are delivered by Bud AI Foundry, which runs on Bud GPU Foundry as a tenant like any other — no private interface, no exemption. Bud GPU Foundry meters capacity; Bud AI Foundry meters tokens. Two meters, one truth.
Open source, sovereign by design
Apache 2.0, so the stack that governs your fleet can be audited rather than trusted. Delivered as signed images and versioned charts into clusters you run; an air-gapped site is an ordinary deployment. Regions are declared by the operator, so data residency is a placement record, not a setting someone asserts.
Every rack sold a tray at a time. Every machine returned with evidence.
Rack-scale systems are not hosts: their trays share one interconnect domain, switch trays, power shelves and liquid cooling. Bud GPU Foundry enrolls the rack as the one unit it is, sells it as bare metal in the units a tenant can hold — a tray, several trays or the whole rack — and takes the rack's shared state into account everywhere it matters.
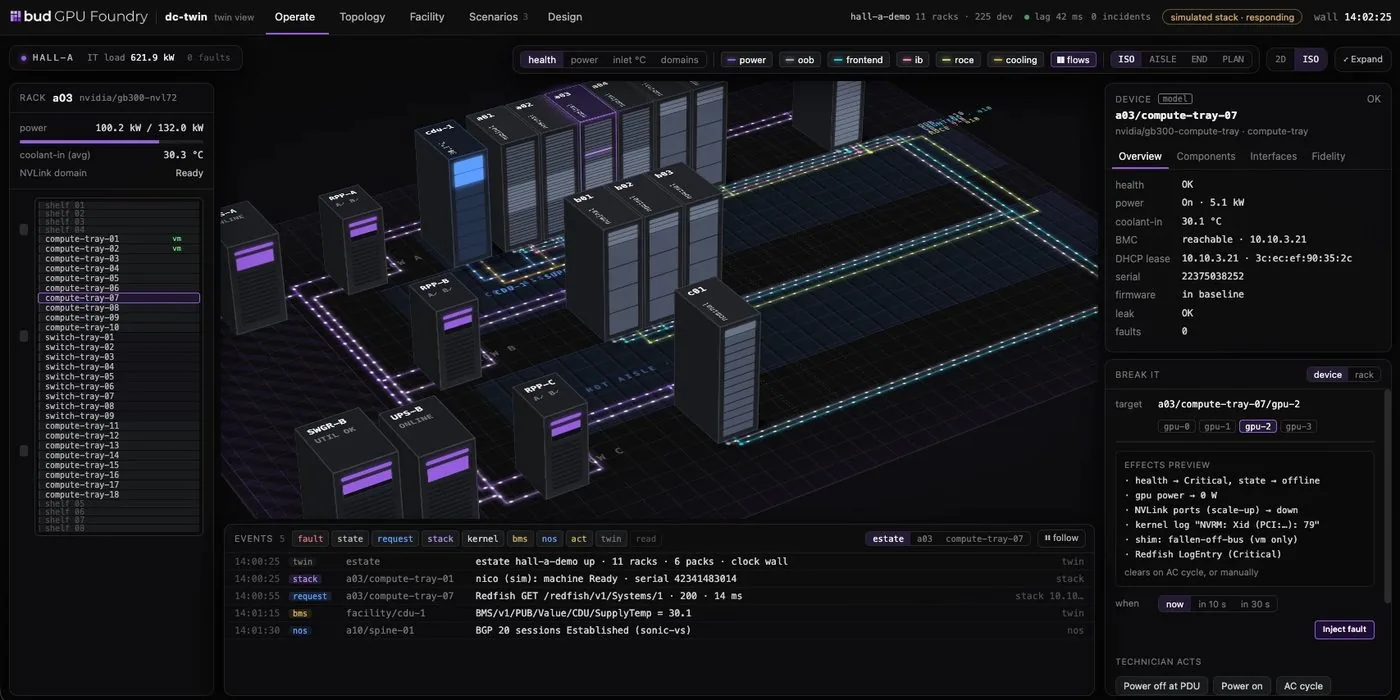
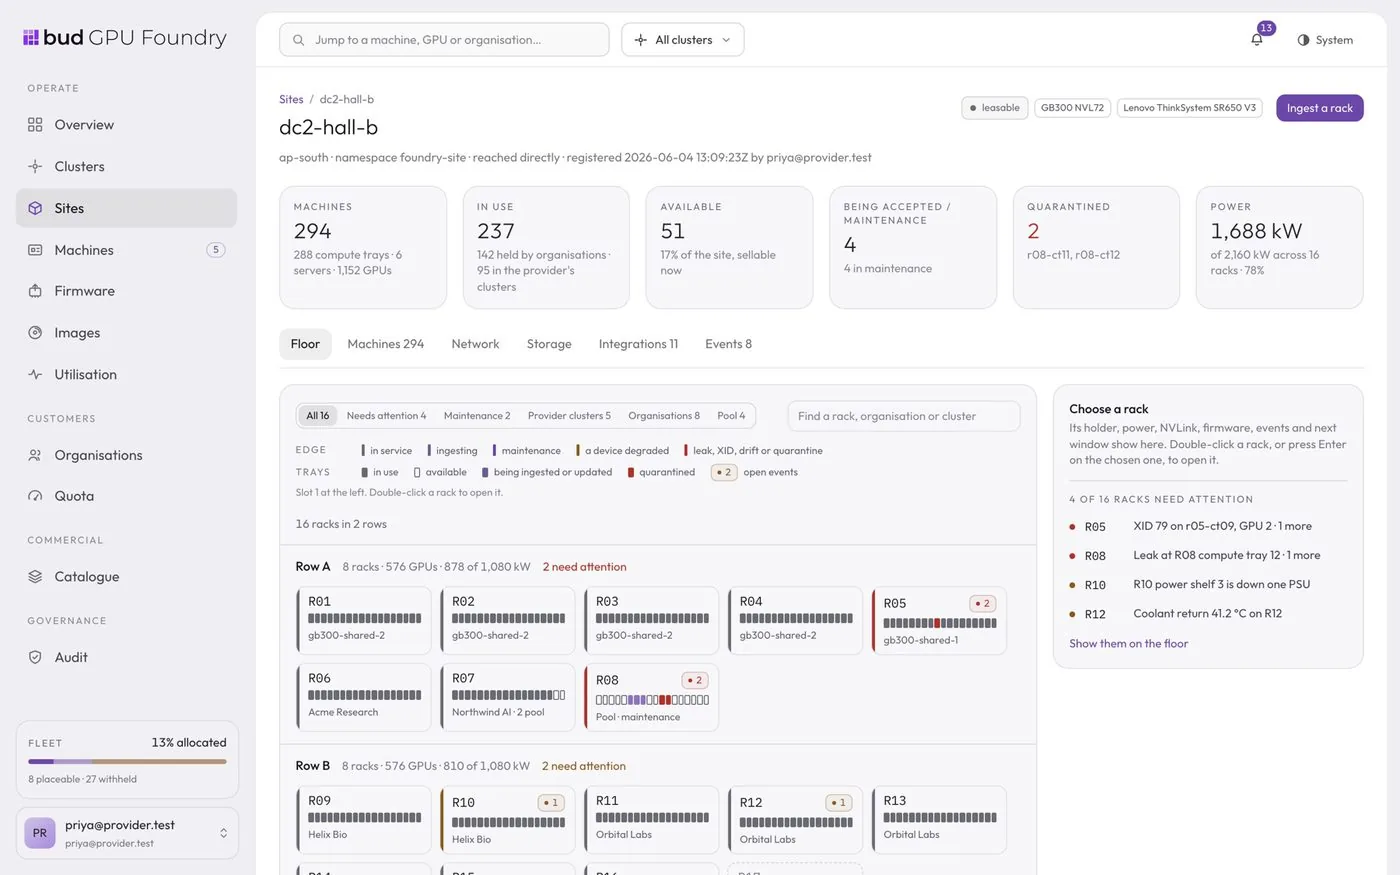
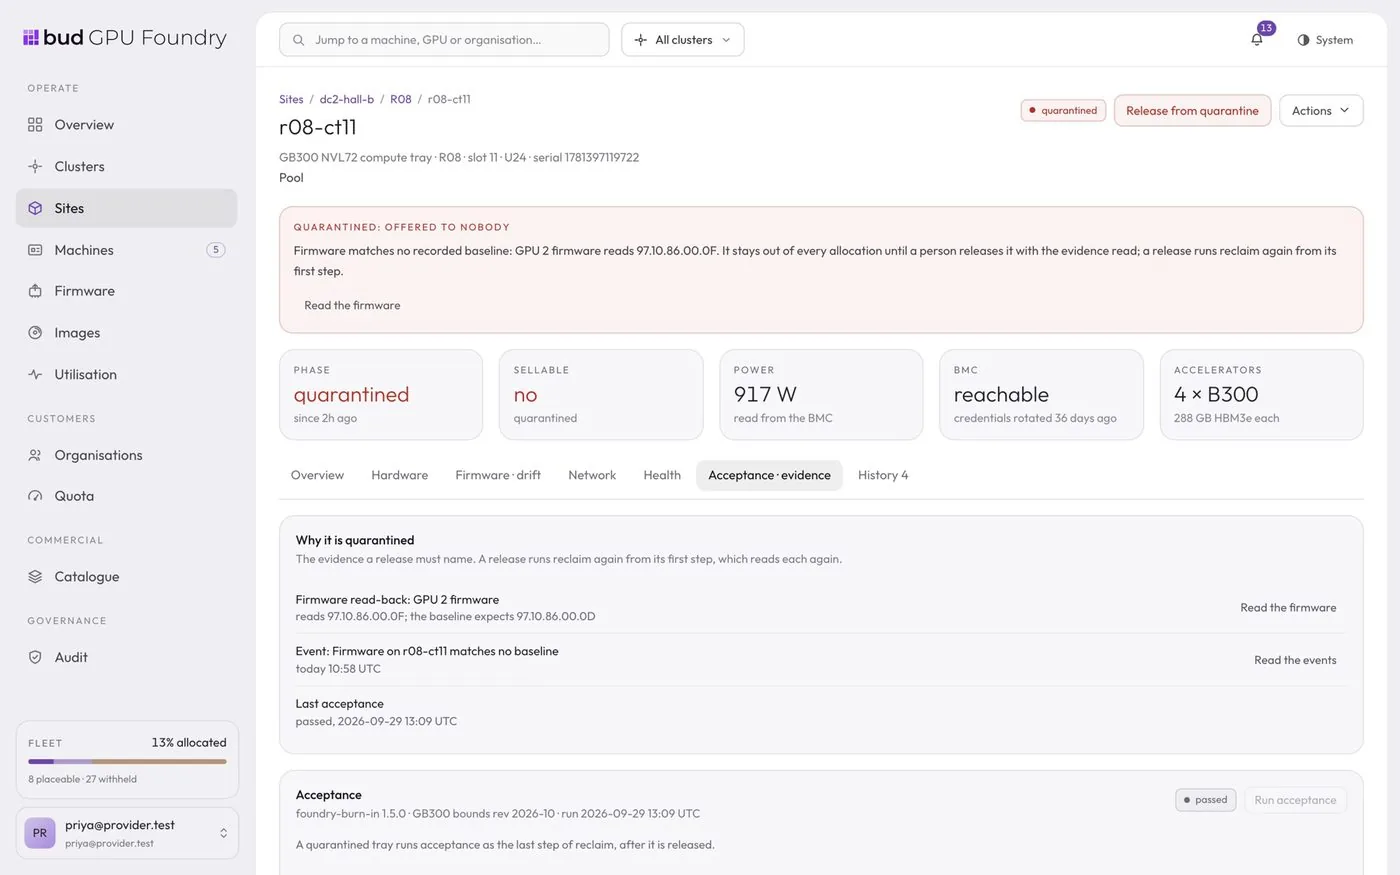
The tray is the unit of sale
Trays are leased whole, as machines, or built into a tenant's cluster, with the same hand-over, reclaim and host-hour billing as any other machine. A unit of several trays is placed inside one interconnect domain, and a rack whose cooling, power or interconnect is degraded offers nothing that depends on it.
Reclaim: every step, every return
Firmware is read back out of band against its generation's baseline, every disk is sanitized, accelerator memory is cleared and acceptance is re-run. A machine that fails any step is quarantined, never resold, and the evidence is kept for the deletion period.
Nothing a tenant holds is touched unannounced
Firmware installs only from packages whose vendor signature verifies at import, air-gapped sites included. Rollouts run in waves, and held machines go last, inside a maintenance window the tenant can accept or move.
Many tenants on one infrastructure, with nothing else shared.
Your own departments, a service provider's mutually untrusting customers, a reseller's sub-organizations and a sovereign customer can all run on the same fleet at once. What differs between them is recorded as a property of the organization, never as a separate deployment.
Isolation is a claim about the unit sold
Each sellable unit names exactly one service class, one isolation mechanism, one metering basis and the tenant classes it may be sold to. A unit binds to machines by what the hardware publishes about itself, so one catalog serves a fleet of mixed generations without a unit landing on the wrong silicon.
Two tenant classes, one platform
Enterprise tenants get every grade, chargeback against internal budgets and a quota ceiling. Service-provider tenants get only grades enforced in hardware or by the fabric, prepaid balance by default, and the full enforcement ladder. The API, the console, the lifecycle and the guarantees never change.
A usage feed for someone else's billing
Metered usage is a continuous, replayable feed keyed on the same windows the platform's own invoices read, so a reseller can rate it in their own system. What they charge is theirs; what was consumed is one number.
Price it, cap it and invoice it from the same log.
Price books per segment, cost floors and margin per unit, commitments, interruptible capacity, spend caps, nested resellers and white-label are native to the platform, not bolted on. The usage on a screen, the figure on an invoice and the number an enforcement decision is made on are the same number.
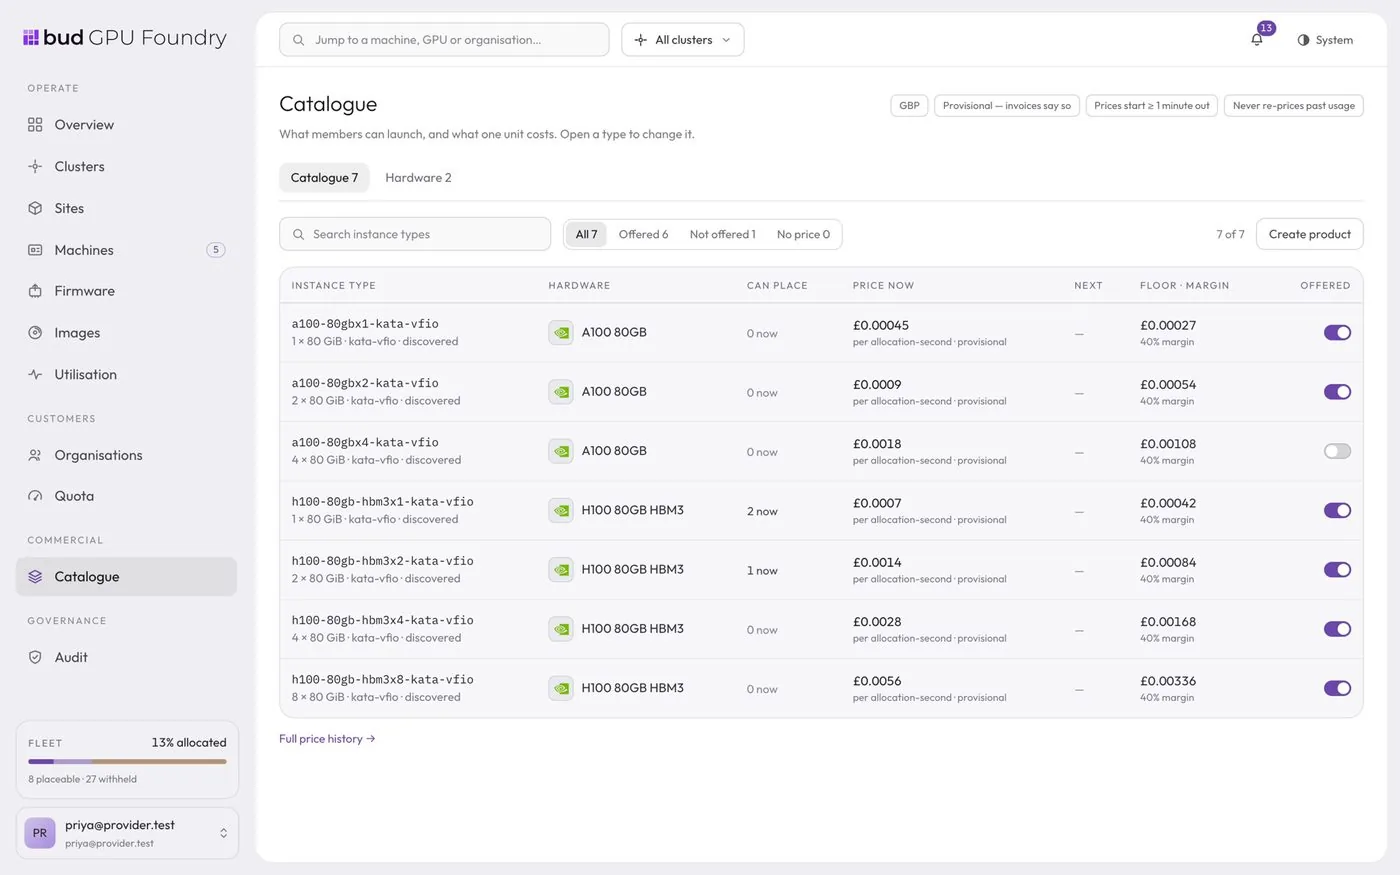
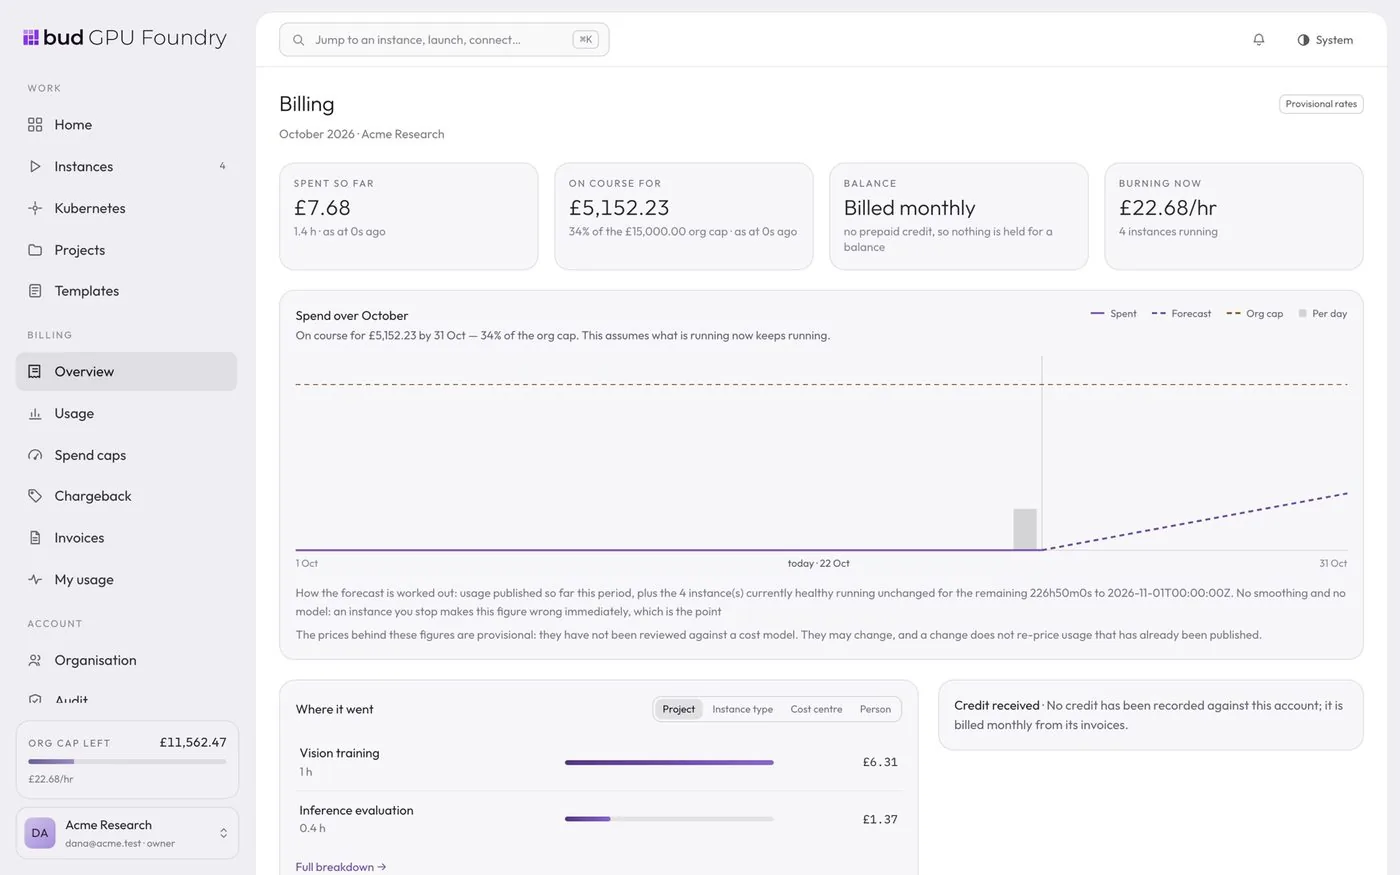
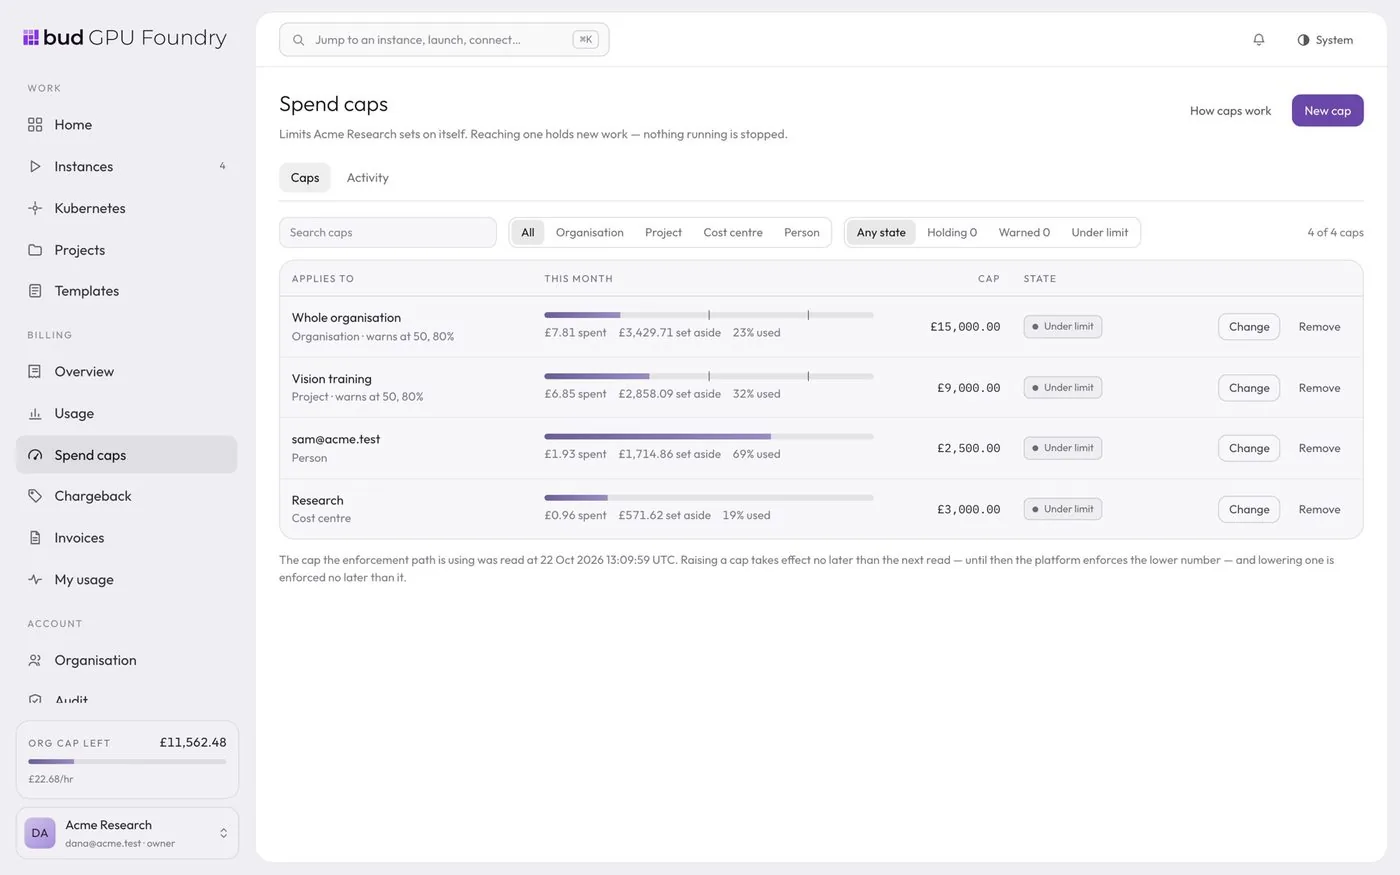
Nothing published below its floor
Every unit's price derives from a cost model covering capacity, power, network, storage and support. Achieved margin is reported per unit at least monthly, and a price below the computed floor needs a recorded decision.
Commitments and interruptible capacity
Term commitments at a discount, backed by a reservation ledger that guarantees the capacity exists. Interruptible capacity at a published discount, with notice never shorter than the tenant's declared checkpoint interval.
Credits without a claim
An availability commitment with a credit schedule, computed from platform telemetry and offered without the tenant having to detect the breach. Contract tenants are billed in arrears, with purchase-order references, and never suspended automatically.
Five ways to consume the same fleet.
A machine, a guest, a cluster, a scheduler or a container. Each is an entry in the same catalog, carries one isolation mechanism and one metering basis, and is watched by the same lifecycle informer. Choose by what your work needs, not by which product your vendor sells.
| Service class | What you receive | Isolation | Metered on |
|---|---|---|---|
| Bare metal | A physical accelerator host provisioned to an operating system you choose, on your own network and storage, reclaimed with verified erasure. Power and break-fix are API calls. Rack-scale systems are sold here too: a tray, several trays or the whole rack. | Sole occupancynobody else resident · returned with evidence | node-hours |
| Virtual machine | A hardware-virtualized guest with its own kernel, accelerators passed through at the hardware level, a boot volume, a console and a power-state lifecycle. Snapshots and private images. | No shared kernelnever a shared kernel with another tenant | allocation-seconds |
| Kubernetes | A conformant control plane of your own, with accelerator node pools from the same catalog, your storage classes and your network, reached without a standing credential. | Dedicated control planeper-tenant node pools · brokered access | node-hours · per cluster |
| SLURM | An HPC cluster with login nodes, partitions, quality-of-service classes and fair share, whose accounting reconciles to the platform's own record. Keep your job scripts and module trees. | Per-tenant clusterlogin nodes through the same gateway | node-hours |
| Serverless container | A workload declared as an image, a command and a shape, placed on the grade the catalog resolved, reachable by shell, terminal or a published address. Scale to zero, wake on demand. | Per gradewhole node to hardware partition | allocation-seconds · GPU-seconds · VRAM-GB-hours |
NVIDIA's tools run the rack. Bud GPU Foundry runs the business on it.
Bud GPU Foundry is often mistaken for NVIDIA's software or compared with Rafay. NVIDIA's reference software for GPU clouds provisions, schedules and monitors, but none of it meters or invoices a tenant. Rafay sells capacity on a closed platform built around NVIDIA. Bud GPU Foundry is the open layer that turns any vendor's fleet into a governed, metered, invoiced service.
Rafay — a closed GPU-cloud platform, NVIDIA-led
- Proprietary, priced per node; NVIDIA AI Cloud-Ready validated, with Cisco and Dell among its partners
- Certified with NVIDIA Run:ai and deploys it as a one-click catalog item, alongside its own GPU sharing (passthrough, MIG, time-slicing)
- Bare metal, VMs, Kubernetes, SLURM, notebooks and inference, with white-label portals and SKU management
- Token Factory since April 2026; usage is metered, with rating and invoicing handed to billing partners
- Calls itself hardware-agnostic; its marketing and named references are NVIDIA-only
On features, Rafay is the closest match in this lane. The difference is license, silicon, how the bill is produced, and how much of the hardware's lifecycle the platform owns.
Parity on the service, further on the business
- Open source under Apache 2.0 — the stack that governs your fleet can be audited, forked and kept
- NVIDIA, AMD, Intel, Qualcomm and Huawei in one catalog, mixed vendors and generations in one fleet
- Rating, invoices, chargeback, prepaid and contract billing native — from the same log as the meter, which starts at healthy
- Nested resellers with quota in whole units and a replayable usage feed, and no route into a customer's work
- Firmware baselines, reclaim with evidence and racks sold a tray at a time, backed by thirty tested guarantees
Above tokens, the rest of Bud Novaria AI OS — training, grounding, guardrails and agents — runs on the same fleet under the same tenancy and audit trail.
If your fleet is NVIDIA end to end and you want a commercially supported Run:ai deployment, NVIDIA validation, or a SaaS-hosted controller you do not run yourself, Rafay is the shorter path today. It has the longer list of named neocloud and telco customers and a wider partner channel.
Platform risk. Ask what happens to an NVIDIA-certified control plane when the next rack is not NVIDIA. Bud GPU Foundry answers with an open stack and 600+ supported accelerator SKUs across five vendors.
Where you are starting from. Greenfield fleets run on Bud GPU Foundry today. A migration path for Rafay-managed fleets is on the roadmap.
Current as of Q4 2026 · Rafay facts from its own published materials, checked 30 Oct 2026 · Full capability matrix in the product brief · Talk to a solutions architect
Refusals as specified as its features.
Bud GPU Foundry is held to thirty guarantees, stated in the negative. Each is closed by an automated check that attempts the forbidden behavior and fails if it succeeds. Most describe something that happens routinely elsewhere in this market. Six of them:
- 01Never bill for capacity that never became healthyMetering derives from the phase log and starts at one phase, and no other.
- 02Never display capacity it cannot placeAvailability is derived from placeability per cluster, with a freshness stamp on every figure.
- 13Never expose a tenant to another tenant's residual accelerator memoryMemory clearing is verified per hardware generation before a device is re-offered.
- 18Never let a reseller see inside its customers' workA reseller reaches quota, consumption and spend; never a workload, a session or a log line.
- 23Never offer a machine again after a tenant changed its firmwareReclaim reads every component back out of band; a mismatch quarantines.
- 29Never smooth, clamp, interpolate or discard a metered quantity before it is ratedThe quantity rated is the quantity metered.
All thirty, with what holds each one, are in the product brief.
The full story, in depth.
The five service classes in full, the isolation grades and tenant classes, the seven lifecycle phases and the reason vocabulary, quota and placement, rack-scale operations and reclaim, billing, the thirty things Bud GPU Foundry will never do — and every headline number with its basis.
Product Brief
Bud GPU Foundry Product Brief
The deep-dive product reference
Service classes, shape resolution, tenancy and isolation grades, the observed lifecycle, rack-scale operations and reclaim, network and storage, access and identity, billing, a tour of both consoles, and the full comparison with Rafay and NVIDIA's own software.
Read the product briefWhite Paper
Bud GPU Foundry Whitepaper
The GPU-as-a-Service Control Plane
Five service classes from one catalog, isolation scoped to the unit sold, metering that starts at healthy and nowhere earlier, every machine returned with evidence, and the thirty guarantees the platform is held to.
Read the white paperBud GPU Foundry is released under Apache 2.0. The public repository link will appear here at the open-source release.
Put your fleet on it.
The fastest way to see what a GPU-as-a-service control plane does for the accelerators you already own is a proof-of-concept on your infrastructure, with your tenants.